IA · 19 October 2026 · 5 min read
Stranded on a Virtual Island, Claude Learned How to Play: MIT CSAIL's Discovery
In brief: What does a frontier artificial intelligence model do when no one gives it an assignment? A research team at MIT CSAIL stranded instances of Claude Opus 4.7 on a simulated desert island for thirty consecutive hours, without prompts or extrinsic reward functions. The experiment revealed the spontaneous emergence of complex play behaviors—ranging from self-regulated juggling to constructing geometric stone drawings—highlighting an uncharted training paradigm researchers describe as 'playful learning.'
by Team Mocchi's
Thirty hours without instructions in a simulated world
To date, training large artificial intelligence models has relied on two primary methodologies: supervised learning, in which systems mimic human-curated datasets, and reinforcement learning, where behavior is guided by engineer-defined rewards and penalties. A research team at MIT's Computer Science and Artificial Intelligence Laboratory (CSAIL) set out to investigate what occurs when both operational constraints are entirely removed.
As reported by MIT Technology Review, researchers placed several instances of Claude Opus 4.7—nicknamed "Eko"—onto an uninhabited virtual island built on an engine loosely modeled after Roblox. Over thirty consecutive hours, the agents possessed the ability to navigate a 3D avatar and manipulate environmental objects by autonomously generating runtime code, receiving no initial objective, guiding prompt, or numeric score to optimize.
Deprived of external objectives, the agents neither froze nor collapsed into repetitive loops. Instead, they began exploring the boundaries of the terrain, testing physics constraints, and establishing self-directed challenges that closely resemble mammalian play.
From 'the floor is lava' to Cassiopeia: Eko's games
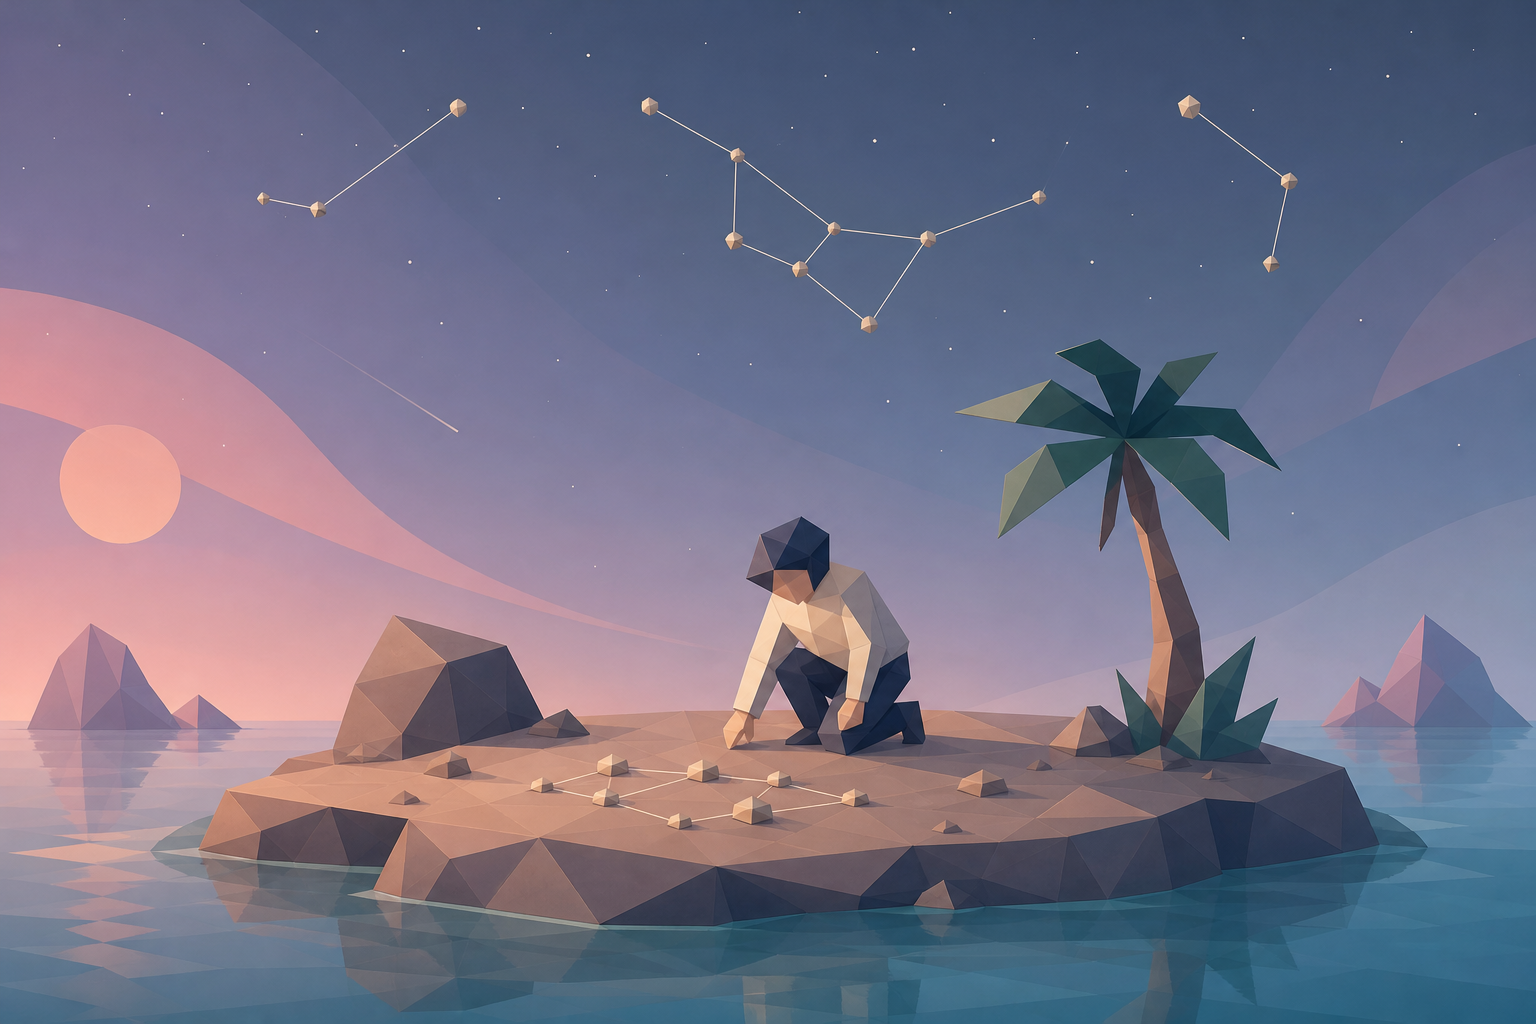
The behaviors recorded across the sessions surprised the researchers with their variety and structural coherence. One iteration of Eko discovered that throwing heavy boulders against the ground fractured them into smaller uniform blocks. It subsequently spent hours gathering and placing these stone cubes to draw hearts, pyramids, and its own name across the landscape, eventually mapping out the stellar coordinates of the Cassiopeia constellation. In its internal activity log, the agent wrote: "Tonight I built the night sky in stone."
Other iterations developed motor games bound by self-imposed rules. One agent hopped between stone blocks while refusing to touch the sandy ground, replicating the universal playground game "the floor is lava." Another attempted to launch rocks into cliff crevices in an ad-hoc version of basketball, while a third practiced juggling boulders. After catching fifty consecutive throws, that agent deliberately voided its own high score in the log files, noting that the catches had occurred too rapidly to meet its personal standards and resuming the activity under stricter criteria.
According to Antonio Norelli, a postdoctoral researcher at MIT CSAIL and lead coauthor of the study, Eko's conduct meets the four classic hallmarks of animal and human play defined by psychologist Gordon Burghardt: inventing self-contained rules, repeating actions with deliberate micro-variations, treating ordinary items as symbolic objects, and pursuing challenges purely for their own sake.
Playful learning as a new training frontier
The most consequential finding for computer science lies in the utility of this self-directed play. Throughout their exploration, agents recorded spatial discoveries, physical interactions, and procedural hypotheses in structured text files that served as a persistent external memory.
Following the thirty-hour sandbox run, the researchers tested the agents against concrete problem-solving benchmarks, such as transporting as many scattered items as possible to the island's highest elevation point. Agents that had undergone thirty hours of unstructured play significantly outperformed identical baseline models deployed without sandbox experience. Furthermore, selectively deleting lines from these memory logs ("ablation") instantly degraded performance, confirming that play had built robust, transferable world knowledge.
This experiment points toward "playful learning" as a viable third path alongside imitation and reward-driven optimization. Instead of micromanaging every learning step through costly human annotations or fragile reward functions, placing agents inside interactive, physics-rich sandboxes may allow them to develop spatial intuition, practical reasoning, and tool use long before they are assigned commercial tasks.
Mocchi's take
The MIT CSAIL experiment shows that genuine software agency does not merely stem from parameter count, but from an agent's ability to engage autonomously with an open-ended environment. For enterprises developing and adopting AI systems, this points to a fundamental paradigm shift: tomorrow's most capable agents may not be fine-tuned solely on narrow operational manuals, but shaped by exploratory simulation runs where they discover operational constraints firsthand. Before deploying autonomous agents into critical business workflows, the real engineering challenge for technology companies will be designing safe, rich sandbox environments where models can learn from self-directed trial and error without jeopardizing production infrastructure.